How to Extract Article Titles, Dates, Authors, and Metadata in 2026: A Practical Guide for AI-Driven Web Scraping
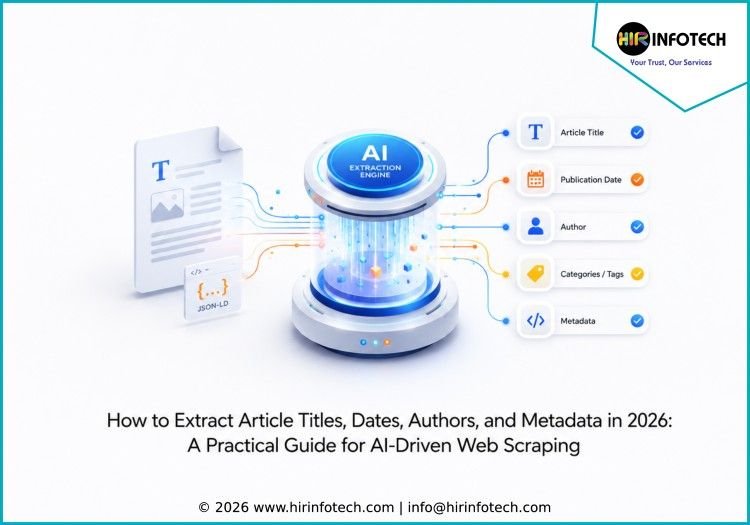
Introduction Content data has become a critical business asset in 2026. Companies tracking competitors, monitoring news, training AI systems, conducting market research, or building content intelligence platforms increasingly rely on accurate extraction of article titles, publication dates, author information, and metadata. The challenge is no longer finding data—it is extracting structured, reliable information at scale. Why Article Metadata Matters for Businesses Article pages contain more than visible text. Behind every article exists structured information that helps businesses understand content context, authority, freshness, and relevance. Common article metadata fields include: For businesses, this information supports multiple operational and strategic functions. Common business use cases Content intelligence platforms Organizations monitor publishers, industry portals, and blogs to identify emerging trends. Media monitoring PR and communications teams track articles mentioning brands, executives, products, or competitors. AI model training and retrieval systems Large datasets require clean metadata structures to improve search quality and contextual understanding. Market research Analysts aggregate content across multiple sources and classify information by category, author, and publishing patterns. SEO and digital marketing Teams evaluate publishing frequency, content topics, and competitor strategies. Without structured extraction, teams often spend significant time cleaning inconsistent datasets. Challenges of Extracting Article Titles, Dates, Authors, and Metadata Many organizations assume article extraction is straightforward until they begin processing thousands of websites. Modern websites create several technical challenges. Dynamic website structures Traditional scrapers frequently depend on fixed HTML elements. For example: A fixed extraction rule rarely works across different domains. JavaScript-rendered pages Many publishers use modern front-end frameworks that load content dynamically. Standard crawlers often fail to detect: Inconsistent metadata standards Although schema formats exist, implementation varies considerably. Common structures include: Businesses often receive fragmented or incomplete outputs. Frequent layout changes Publishers redesign websites regularly. When layouts change: For businesses relying on continuous data feeds, interruptions create operational risks. Duplicate and low-quality data Extraction at scale often produces: Data quality quickly becomes a larger challenge than extraction itself. How AI-Driven Web Scraping Solves These Problems Traditional rule-based scraping still has value, but 2026 expectations increasingly demand AI-assisted extraction systems. AI-driven web scraping combines: Instead of relying solely on fixed page structures, AI models identify patterns across different sources. Smarter title extraction AI systems recognize article titles based on: Even if a publisher changes page design, extraction accuracy remains more stable. Better author identification Author information appears in multiple forms: AI-based extraction systems can compare signals and identify the most reliable source. Accurate date recognition Dates create major inconsistencies: Examples include: AI systems normalize dates into standardized formats for downstream analytics. Metadata enrichment Advanced workflows often enrich extracted data with: This turns raw article data into actionable business intelligence. Step-by-Step Process for Extracting Article Metadata Businesses considering article extraction projects should think beyond simply collecting HTML. A practical workflow generally looks like this. Step 1: Identify target sources Determine: Source selection influences technical complexity. Step 2: Analyze page structures Review: Early analysis reduces later maintenance costs. Step 3: Build extraction logic Identify fields such as: Step 4: Handle rendering and anti-bot challenges Modern extraction systems often require: Step 5: Validate and clean outputs Quality checks may include: Step 6: Deliver structured datasets Typical output formats include: Why Accuracy Matters More Than Volume in 2026 Many organizations initially focus on extraction scale. However, inaccurate metadata creates larger downstream problems. Examples include: Poor AI recommendations Missing or incorrect metadata reduces search and recommendation quality. Misleading business reports Incorrect publishing dates can distort trend analysis. Weak competitive intelligence Incomplete author or topic information creates gaps in market monitoring. Analytics failures Dashboards built on inconsistent datasets become difficult to trust. Businesses increasingly prioritize: How Hir Infotech Supports AI-Driven Article Metadata Extraction Article metadata extraction aligns directly with modern AI-driven web scraping requirements because businesses increasingly need reliable, structured content intelligence rather than raw page data. Hir Infotech specializes in AI-driven web scraping and data extraction workflows designed for organizations that require scalable data collection across dynamic websites and large datasets. Its capabilities include intelligent crawling, structured extraction pipelines, real-time processing, custom scraper development, and multi-format data delivery. For businesses building content intelligence platforms, market research systems, media monitoring solutions, or AI applications, extracting article titles, authors, dates, and metadata often involves more than basic scraping scripts. Dynamic websites, JavaScript-rendered pages, anti-bot systems, and changing page structures require adaptive extraction approaches. Hir Infotech’s AI-based extraction capabilities support these scenarios by creating structured pipelines that can collect, normalize, and organize web data for operational use. Organizations can integrate extracted information into CRM platforms, analytics tools, business intelligence systems, or internal applications without spending significant time on manual processing. For businesses operating across India and international markets, scalable extraction infrastructure and clean data delivery can reduce operational complexity while improving decision-making speed. What Businesses Should Evaluate Before Choosing a Web Scraping Partner Not all extraction providers deliver the same level of reliability. Decision-makers should evaluate: Technical capabilities Assess whether providers support: Data quality processes Ask questions such as: Compliance and governance Responsible providers should address: Integration support Business value increases when extracted data connects directly to: Scalability Solutions should support future growth without constant redesign. Frequently Asked Questions What is article metadata extraction? Article metadata extraction is the process of collecting structured information from articles, including titles, publication dates, authors, categories, tags, and related content attributes. Why are publication dates and author details important? Dates and author information help businesses determine content relevance, authority, content freshness, and publishing patterns for analytics or competitive intelligence. Can article metadata be extracted from JavaScript websites? Yes. Modern AI-driven web scraping solutions use rendering technologies and intelligent extraction methods to collect data from JavaScript-based websites. Is metadata extraction useful for AI systems? Yes. Structured metadata improves search accuracy, retrieval quality, recommendation systems, and AI model context understanding. How does Hir Infotech support metadata extraction projects? Hir Infotech provides AI-driven web scraping services that help organizations collect, structure, and deliver metadata from websites at scale for analytics, research, and business intelligence workflows. Conclusion Understanding how to extract article titles, dates,