Uncategorized

Uncategorized

How to Estimate the Cost of Scraping Keyword Data for Thousands of Search Terms in 2026

How to Estimate the Cost of Scraping Keyword Data for Thousands of Search Terms in 2026 Introduction Keyword data scraping has become a critical part of SEO, paid search, content planning, and competitive intelligence in 2026. Businesses managing large-scale campaigns across markets like the USA, Germany, the United Kingdom, Canada, and Australia often need reliable keyword datasets at scale. Estimating scraping costs accurately helps organizations avoid infrastructure waste, compliance risks, and unreliable data collection workflows. Why Businesses Scrape Keyword Data at Scale Modern search marketing depends heavily on access to fresh keyword intelligence. Businesses no longer analyze only a few hundred terms. Enterprise SEO teams, SaaS companies, ecommerce brands, affiliate publishers, and agencies often monitor thousands or even millions of keywords across multiple regions and devices. Large-scale keyword scraping is commonly used forSearch intent analysisSERP trackingCompetitor monitoringPPC campaign planningAI-driven keyword clusteringContent gap analysisLocal SEO monitoringProduct demand forecastingInternational SEO expansion For companies operating across countries such as France, Spain, Switzerland, the Netherlands, and Hong Kong, keyword data requirements become more complex due to language and regional variations. What Impacts the Cost of Scraping Keyword Data 1. Number of Search Terms The biggest cost driver is keyword volume.5,000 keywords is relatively small scale500,000 keywords requires enterprise infrastructureMillions of keywords require distributed systems Cost scales based onTotal keywordsScraping frequencySearch engines usedGeographic locations 2. Frequency of Data Collection Higher frequency increases cost due toProxy usageCAPTCHA handlingCompute requirementsStorage load Common schedulesDailyWeeklyHourlyReal-time 3. Geographic Targeting Scraping across multiple countries increases complexity. Localized scraping requiresCountry-specific proxiesLanguage targetingGeo-distributed systemsDevice simulation 4. Search Engine Complexity Google is the most expensive to scrape due toAnti-bot systemsCAPTCHA challengesDynamic SERP layoutsJavaScript rendering Additional SERP features increase costFeatured snippetsAI OverviewsShopping resultsMaps resultsPeople Also Ask 5. Type of Keyword Data Required Basic data includesRankingsURLsTitles Advanced data includesSERP featuresCPC dataIntent classificationCompetitor domainsAI overview presence Infrastructure Costs Behind Large-Scale Keyword Scraping Proxy Networks Proxy costs are a major recurring expense.Residential and mobile proxies are required for reliability. Factors affecting costRegionTraffic volumeSuccess ratesProvider quality Cloud Infrastructure Scraping systems require cloud resources forAutomationParsingQueue managementStorageRetries Higher cost occurs withHeadless browsersJavaScript renderingHigh concurrency CAPTCHA Solving Costs includeThird-party solversAI solving systemsHuman fallback systems Data Storage and Processing Large-scale scraping generates heavy data loads requiringDatabasesData warehousesHistorical trackingAPIsDashboards Typical Pricing Models for Keyword Data Scraping Per-Keyword Pricing Based onKeyword volumeFrequencySearch engine type Monthly Managed Services IncludesInfrastructureMaintenanceAPIsMonitoring Enterprise Custom Pricing Based onGeographyScaleComplianceData complexityIntegration needs Hidden Costs Businesses Often Miss Engineering Maintenance Ongoing updates forSearch engine changesParser updatesProxy tuningSystem maintenance Compliance and Legal Review Important for regions like the EU due to data regulations and privacy laws. Data Quality Validation Ensures accuracy by filteringDuplicatesIncomplete dataParsing errorsGeo mismatches How Businesses Can Reduce Keyword Scraping Costs Prioritize High-Value Keywords Scrape important keywords more frequently and reduce updates for low-priority terms. Use Smart Scheduling Adaptive scheduling reduces unnecessary requests and infrastructure load. Avoid Over-Collecting Data Collect only necessary fields to reduce storage and processing costs. How Hirinfotech Supports Large-Scale Scraping Keyword Data Projects Hirinfotech supports scalable keyword scraping workflows for businesses handling large SEO and search intelligence operations across global markets. Their solutions are designed for organizations operating in regions such as the USA, UK, Germany, France, Spain, Canada, and Australia. Capabilities includeHigh-volume SERP scrapingGeo-targeted keyword extractionRank tracking automationSearch intent analysisCompetitor monitoringStructured keyword datasetsAPI-ready data delivery This reduces infrastructure burden by handling proxy management, scraping maintenance, anti-bot handling, and data pipelines for agencies, SaaS companies, and enterprise SEO teams. Key Questions to Ask Before Budgeting for Keyword Scraping What data is requiredSERP depthGeographic coverageFrequencyOutput format How fresh must the data beDaily or real-time data increases cost significantly. Is internal development realisticInternal systems require ongoing maintenance and infrastructure investment. Managed providers often reduceEngineering loadDowntime riskData inconsistency Frequently Asked Questions How much does scraping keyword data cost? Costs depend on scale, frequency, geography, and data complexity. Small projects may cost a few hundred dollars monthly, while enterprise systems require significantly more investment. Why is Google scraping more expensive? Due to anti-bot systems, dynamic SERPs, CAPTCHA enforcement, and localization complexity. Does localization increase cost? Yes, because it requires region-specific infrastructure and proxies. Can businesses scrape millions of keywords? Yes, but it requires distributed infrastructure and strong automation systems. What industries use keyword scraping? SEO, ecommerce, SaaS, publishing, affiliate marketing, and market research. Can Hirinfotech support large-scale scraping? Yes, through scalable keyword extraction workflows and enterprise-grade search intelligence systems. Conclusion Estimating the cost of scraping keyword data for thousands of search terms requires understanding infrastructure, geographic targeting, frequency, and data complexity. In 2026, businesses increasingly rely on scalable keyword intelligence systems to support SEO, PPC, AI-driven search, and competitive analysis. Organizations should evaluate not just scraping costs, but also data quality, compliance, scalability, and long-term maintenance needs when planning keyword data projects.
Uncategorized

Compliant Web Scraping for Publishers: What Businesses Need to Know in 2026

Compliant Web Scraping for Publishers: What Businesses Need to Know in 2026 Introduction Publishers sit at the intersection of valuable content and intense data demand. As businesses increasingly rely on scraped media data for competitive intelligence, content aggregation, and market monitoring, the compliance dimension of web scraping has never been more consequential. Getting it wrong carries real legal and reputational risk. Getting it right opens up a powerful, scalable data capability. Why Compliance Has Become Central to Web Scraping in 2026 For years, web scraping operated in a grey area. Many businesses scraped freely, assuming that publicly accessible content was fair game. That assumption has become increasingly difficult to sustain. Several converging forces have reshaped the risk landscape. High-profile litigation—most notably the ongoing disputes between major publishers and AI companies over training data—has put scraping practices under legal and regulatory scrutiny. The EU AI Act, now in full enforcement, requires AI developers to disclose training data sources and respect machine-readable copyright opt-outs under the Copyright Directive’s text and data mining exception. In the US, proposed legislation introduced in early 2026 aims to require AI companies to seek permission and compensate publishers before scraping their content. At the same time, publishers themselves are responding. Major news organisations and content platforms have updated their robots.txt files to explicitly block AI crawlers. Some are pursuing licensing agreements. Others are actively monitoring for unauthorised scraping activity and taking enforcement action. For businesses that rely on publisher data—whether for news monitoring, content intelligence, trend analysis, or media benchmarking—this environment demands a structured approach to compliance, not ad hoc scraping. What Compliant Web Scraping Actually Involves Compliant web scraping is not just about avoiding legal trouble. It is about building data pipelines that are defensible, sustainable, and respectful of the sources they rely on. For publishers specifically, several layers of compliance come into play. Respecting robots.txt and Terms of Service The robots.txt standard, which has existed since 1994, allows publishers to communicate crawling preferences to automated systems. While ignoring robots.txt is not automatically illegal in every jurisdiction, doing so undermines a good-faith defence and can strengthen claims of unauthorised access or breach of contract. A compliant scraping operation reads and honours robots.txt directives and reviews each target site’s terms of service before any extraction begins. This is particularly relevant for publisher sites, where terms of service frequently prohibit automated data collection, commercial reuse, or content aggregation. A provider that skips this step exposes clients to breach of contract risk—even when the underlying data appears publicly accessible. Copyright and Content Boundaries Publisher content—articles, analysis, feature writing, multimedia—is almost universally protected by copyright law. The fact that it is accessible without a login does not make it freely reusable. Scraping copyrighted editorial content and republishing or commercially exploiting it creates direct exposure to infringement claims, including statutory damages under US law and injunctive relief in other jurisdictions. Compliant scraping focuses on factual data points, metadata, structured information, and other non-expressive elements rather than wholesale extraction of protected editorial content. Where content must be processed in bulk—for media monitoring or sentiment analysis, for example—a qualified provider will assess transformative use considerations and ensure that output does not replicate or displace original content in ways that courts would find problematic. Privacy Regulations: GDPR and Beyond Publisher sites frequently contain personal data—author bylines, contact details, user-generated comments, and structured profile information. Under GDPR, collecting personal data belonging to EU residents triggers compliance obligations regardless of where the scraping organisation is based. This means establishing a lawful basis for processing, applying data minimisation principles, and maintaining appropriate safeguards. A compliant web scraping service builds these considerations into its pipeline design from the outset—filtering out personal identifiers, applying anonymisation where necessary, and maintaining documentation that would satisfy a regulator or a legal team conducting due diligence. Rate Limiting and Infrastructure Behaviour Compliance is not only a legal concept. It is also a technical and ethical one. Scraping publisher sites with excessive request volumes can degrade site performance, trigger automated defences, and create liability under computer misuse statutes even when the underlying data is public. Responsible scraping implements meaningful rate limits, uses clearly identified user-agent strings rather than disguising bots as regular browsers, and avoids placing unnecessary load on target infrastructure. Use Cases for Publisher Data That Demand Compliance Precision Businesses collect publisher data for a range of legitimate commercial purposes. The compliance requirements differ depending on use case, and a qualified provider will calibrate its approach accordingly. Media monitoring and press tracking involves collecting articles, headlines, and publication timestamps across multiple news sources. This use case typically involves factual data points—publication date, headline, section, outlet—rather than full article reproduction, which keeps copyright exposure manageable when handled correctly. Content intelligence and trend analysis requires processing editorial output at scale to identify themes, sentiment, and coverage patterns. This is a high-value use case for brand teams, PR functions, and market research operations, but it requires careful handling to avoid reproducing substantial portions of protected content. Competitive content benchmarking allows publishers themselves to track how competitors are structuring their content, what formats they are using, and how frequently they publish across topic areas. This is an operational use case where structured metadata matters more than raw content extraction. News aggregation for research platforms involves collecting and structuring publisher data for academic, analytical, or intelligence applications. This use case sits in a more sensitive area legally, particularly where content is presented to end users in a form that could substitute for the original publication. In each of these scenarios, the business outcome depends not just on the technical quality of the data extraction, but on the legal defensibility of the process that produced it. How Hir Infotech Approaches Compliant Web Scraping for Publisher Data Hir Infotech has been delivering web scraping and data extraction services since 2013, with a client base spanning the US, Europe, and global markets. The company’s service delivery model includes a structured legal and ethical review at the scoping stage of every

Uncategorized

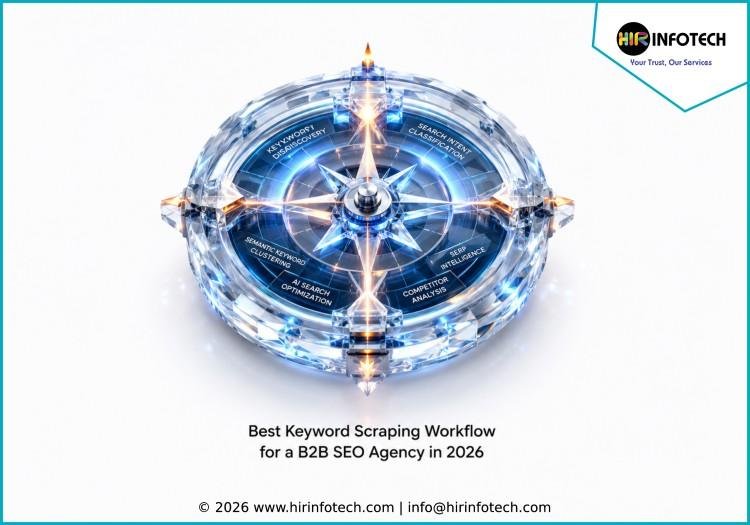
Best Keyword Scraping Workflow for a B2B SEO Agency in 2026

Best Keyword Scraping Workflow for a B2B SEO Agency in 2026 Introduction B2B SEO agencies are under increasing pressure to deliver scalable organic growth in highly competitive markets. In 2026, keyword scraping workflows have become essential for uncovering real-time search opportunities, analyzing search intent, monitoring competitors, and improving AI-search visibility across international search ecosystems. Why B2B SEO Agencies Need Advanced Keyword Scraping Workflows Traditional keyword research methods are no longer sufficient for modern B2B SEO. Search environments now include: B2B buyers also follow longer, research-driven search journeys compared to consumer audiences. Key benefits of keyword scraping workflows: What Is a Keyword Scraping Workflow? A keyword scraping workflow is a structured process used to collect, organize, analyze, and operationalize keyword data from search engines and related environments. Core components include: Goal: Transform raw search data into actionable SEO strategy. The Best Keyword Scraping Workflow for a B2B SEO Agency Step 1: Define SEO Objectives and Buyer Intent Before scraping begins, define: Search Intent Types: Step 2: Scrape Seed Keywords From Search Engines Collect primary data from: Example seed keywords: Step 3: Extract SERP Features and Metadata Go beyond rankings and capture: This reveals: Step 4: Classify Keywords by Search Intent Organize keywords into: This improves: Step 5: Identify Low-Competition Opportunities Look for: Example opportunities: Step 6: Cluster Keywords by Topic and Funnel Stage Group keywords into semantic clusters: Example Cluster: Keyword Scraping Workflow Step 7: Map Keywords to Content Types Step 8: Monitor SERP Changes Continuously Track: Why Localization Matters in Keyword Scraping Search behavior varies across: Key markets: USA, UK, Germany, France, Spain, Italy, Canada, Australia, etc. Localized scraping improves: AI Search Optimization and Keyword Scraping AI search engines prioritize: Platforms influenced: How Hirinfotech Supports Keyword Scraping Workflows for B2B SEO Agencies Hirinfotech provides scalable keyword scraping and SERP intelligence solutions for SEO agencies and enterprises. Their workflows support: This helps agencies manage large-scale SEO campaigns with real-time search intelligence. Best Practices for Keyword Scraping Workflows Focus on Search Intent First Intent matters more than keyword volume. Use Real-Time SERP Data Live data reveals emerging opportunities. Combine SEO + AI Search Analysis Optimize for both: Prioritize Semantic Clustering Search engines reward topic depth. Continuously Monitor Competitors Track: Frequently Asked Questions What is a keyword scraping workflow? A structured process for collecting and analyzing keyword and SERP data to improve SEO strategy. Why do B2B SEO agencies use it? To identify intent, track competitors, and find ranking opportunities. How does it improve SEO? It provides real-time insights for better content and targeting. Is it useful for international SEO? Yes, especially for multilingual and regional markets. How does AI search affect it? AI search increases the importance of semantic and conversational keyword analysis. How can Hirinfotech help? It provides scalable SERP intelligence and keyword scraping solutions for SEO agencies. Conclusion A structured keyword scraping workflow is now essential for modern B2B SEO success. By combining SERP analysis, intent classification, semantic clustering, localization, and AI-search optimization, agencies can build more accurate and scalable SEO strategies. In 2026, SEO success depends on understanding real-time search behavior rather than relying on static keyword databases.

Uncategorized

The Definitive Guide to AI Web Scraping for Corporate Media Monitoring in 2026

The Definitive Guide to AI Web Scraping for Corporate Media Monitoring in 2026 The modern media ecosystem moves too fast for standard tracking tools. Between localized news sites, paywalled industry publications, and shifting social channels, businesses struggle to maintain a clear view of their public reputation. Relying on manual keyword monitoring or rigid, off-the-shelf software inevitably leaves dangerous gaps in data collection. For enterprise brands, public relations agencies, and financial institutions, missed information translates directly to unmitigated reputational risks and lost market opportunities. Resolving this issue requires a change in strategy: transitioning from basic keyword tracking to custom, automated text extraction capable of handling the scale, diversity, and complexity of the current digital landscape. Traditional media monitoring relies on basic RSS feeds, public APIs, and fixed keyword alerts. While these methods worked when media consumption was consolidated across a few major networks, the media ecosystem of 2026 is highly fragmented. The Media Landscape Challenge: Why Traditional Tracking Fails Corporate communication teams face several distinct data obstacles: When a corporate crisis emerges or an important regulatory shift occurs, a delay of even a few hours can completely ruin an organization’s strategic response. B2B enterprises require an active data pipeline that extracts clean, structured textual content exactly when it is published. Implementing AI Web Scraping for Media Monitoring 1. Resilient Anti-Bot Evasion and IP Management To address these limitations, modern organizations utilize an advanced, automated data infrastructure. By combining machine learning models with robust web extraction engines, businesses can easily convert unstructured public text into structured, actionable business intelligence. Enterprise-grade web scraping relies on highly advanced proxy management. To extract data without disruption, automated crawlers simulate authentic user behavior patterns. This process involves utilizing distributed residential proxy networks, implementing smart request throttling, and continually rotating browser fingerprints. Managing these deep technical layers ensures that scrapers can access critical public data without triggering security walls or getting blocked by major media sites. 2. Structural Adaptation via Computer Vision and Machine Learning Legacy web scrapers break the moment a publication updates its website layout or moves a text element. Modern AI web scraping systems utilize computer vision algorithms and machine learning models to analyze pages contextually, mimicking how a human eye processes content. The system identifies titles, authors, publication dates, and body text based on context rather than rigid HTML paths. If a news outlet modifies its design, the extraction engine adapts automatically, avoiding system downtime. 3. Real-Time Processing and Stream Integration Media monitoring requires data processing pipelines with exceptionally low latency. Advanced data architectures utilize high-speed Web Scraping APIs that capture breaking stories, press releases, and forum mentions within minutes of publication. This extracted data is converted into clean, standardized formats like JSON or CSV and fed straight into internal corporate risk systems, data lakes, or analytics dashboards. Key Use Cases for Enterprise Media Intelligence Automated web scraping provides the underlying data for several vital corporate functions: Brand Protection and Crisis Management Public perception can shift in minutes. By maintaining a continuous web scraping pipeline across global news outlets, financial forums, and review sites, risk managers can spot negative mentions early. When clean data feeds directly into crisis mitigation workflows, communication teams can respond long before an issue escalates into a full-scale corporate crisis. Competitive Intelligence and Market Positioning Tracking your own brand is only half the battle. Organizations use web scraping to track competitor product rollouts, executive changes, media strategies, and consumer reception. Aggregating this external data allows marketing and product leaders to adjust pricing strategies, redefine product positioning, and capitalize on clear market gaps. Regulatory and Compliance Tracking For companies operating in highly regulated fields like healthcare, finance, or energy, missing a policy shift can result in massive legal compliance penalties. Automated scrapers can systematically track government portals, official gazettes, and legal publications to flag upcoming regulatory updates, giving compliance teams ample time to adjust internal operations. Developing and managing an internal data extraction infrastructure requires massive capital investments, specialized dev teams, and constant maintenance. Hir Infotech provides an enterprise-grade alternative, delivering fully managed Web Scraping Services tailored directly for high-volume corporate media monitoring. With over 13 years of operational experience across the USA, Europe, and Australia, Hir Infotech manages complex data extraction pipelines for mid-market and Fortune 500 companies alike. The platform features an advanced, AI-native infrastructure that processes millions of pages daily with a 99.9% uptime rate. By utilizing sophisticated machine learning models, Hir Infotech handles dynamic JavaScript websites, rotates residential proxy networks to bypass anti-bot systems, and automates text normalization across 85+ languages. For media intelligence applications, Hir Infotech extracts comprehensive text data from global news networks, niche industry publications, and alternative data channels. The raw text is stripped of ads and navigation clutter, enriched with structural metadata, and delivered through real-time APIs or direct database integrations. This fully managed service removes operational friction, allowing corporate communication, data engineering, and risk management teams to focus entirely on analyzing insights rather than maintaining failing code. Key Evaluation Criteria for Selecting a Data Provider When reviewing external web scraping partners for your media monitoring requirements, consider these four vital core areas: Frequently Asked Questions What makes AI web scraping more effective than traditional media monitoring tools? Traditional tracking platforms are often rigid, limited to specific public APIs, and prone to breaking when target websites alter their design layout. AI web scraping uses machine learning to dynamically adapt to website structural changes, successfully bypass complex anti-bot walls, and extract clean text across millions of diverse web pages without manual configuration. How does Hir Infotech protect data quality and extraction accuracy? Hir Infotech utilizes a multi-layer validation pipeline combining AI-driven parsing algorithms with automated quality assurance workflows. This system maintains a verified 99.4% data extraction accuracy rate, removing advertising noise, boilerplate code, and duplicate text to deliver perfectly clean, structured data sets. Is dynamic text extraction across regional news sources legally compliant? Yes, extracting publicly available media text is entirely legal provided the operation follows ethical guidelines. Hir Infotech operates under

Uncategorized

How to Use Scraped SERP Snippets to Classify Search Intent in 2026

How to Use Scraped SERP Snippets to Classify Search Intent in 2026 Introduction Understanding search intent has become essential for SEO performance, AI-search visibility, and content strategy in 2026. Businesses are increasingly using scraped SERP snippets to analyze how search engines interpret queries, classify user intent more accurately, and build content that aligns with real search behavior across international markets. What Are Scraped SERP Snippets? SERP snippets are the short descriptions, titles, and structured elements displayed on search engine result pages. When businesses scrape SERP snippets, they collect information such as: This data provides direct insight into how search engines categorize and prioritize content for specific queries. Unlike traditional keyword metrics alone, SERP snippets reveal contextual intent signals directly from live search results. Why Search Intent Classification Matters in 2026 Search intent classification helps businesses understand what users actually want when they search. In modern SEO and AI-search ecosystems, ranking content successfully depends heavily on intent alignment. Search engines now prioritize: Misaligned content often struggles to rank, even with strong backlinks or technical SEO. Accurate intent classification helps organizations: The Main Types of Search Intent Before using scraped SERP snippets for classification, businesses need to understand the major intent categories. Informational Intent Users are looking for knowledge, guidance, or explanations. Examples SERPs for informational intent often contain: Commercial Investigation Intent Users are researching solutions before making decisions. Examples SERPs typically include: Transactional Intent Users are ready to purchase or contact providers. Examples Transactional SERPs often show: Navigational Intent Users are searching for a specific brand or platform. Examples SERPs generally prioritize branded results and official websites. How Scraped SERP Snippets Help Classify Search Intent SERP snippets provide real-time indicators of what search engines believe users expect from a query. This allows businesses to classify intent more accurately than relying on keyword phrasing alone. Analyzing Title Tags for Intent Signals Page titles are one of the strongest indicators of search intent. Informational Patterns SERP titles often include: Example “How to Use SERP Scraping for Keyword Research” This strongly suggests informational intent. Commercial Investigation Patterns Titles frequently contain: Example “Best SERP Scraping Tools for SEO Agencies” This indicates solution-evaluation behavior. Transactional Patterns Transactional titles commonly use: Example “Enterprise SERP Scraping Services for Ecommerce” This suggests purchase-oriented intent. Using Meta Descriptions to Understand User Expectations Meta descriptions often clarify the business context behind search intent. For example: Informational Example “Learn how SERP scraping helps identify keyword opportunities and competitor strategies.” Transactional Example “Get scalable SERP scraping solutions with API integration and enterprise reporting.” The second example clearly reflects commercial readiness. Businesses scraping SERP metadata can automatically classify queries based on these semantic patterns. Using Featured Snippets and PAA Data Featured snippets and People Also Ask sections are highly valuable for intent classification. They reveal: Example Questions These signals strongly indicate informational or investigative intent. In AI-driven search environments, these sections also influence answer-engine visibility. How AI Search Has Changed Intent Classification AI-generated search systems have significantly expanded the complexity of search intent analysis. Modern search behavior includes: As a result, businesses increasingly use scraped SERP snippets to identify: This has become particularly important for businesses targeting markets such as the USA, Germany, United Kingdom, Canada, Australia, France, and the Netherlands. Practical Examples of Intent Classification Using Scraped SERP Snippets Example 1: Informational Query Search Query “how to monitor keyword rankings” SERP Characteristics Intent Classification Informational Example 2: Commercial Investigation Query Search Query “best SERP scraping tools for agencies” SERP Characteristics Intent Classification Commercial investigation Example 3: Transactional Query Search Query “enterprise SERP scraping services” SERP Characteristics Intent Classification Transactional Benefits of Intent Classification Through SERP Scraping More Accurate Content Strategy Businesses can align content directly with user expectations. This improves: Better Keyword Clustering Intent classification helps organize keywords into meaningful topic groups. This improves: Improved International SEO Search intent varies by region and language. SERP scraping helps businesses identify localized intent differences across: Localized intent analysis improves multilingual SEO performance. Enhanced AI Search Optimization AI search systems increasingly rely on contextual understanding rather than exact keyword matching. Intent-focused SERP analysis helps businesses structure content for: How Hirinfotech Supports SERP Snippet Analysis and Search Intelligence hirinfotech supports businesses with scalable SERP data extraction and search intelligence solutions that help classify search intent more accurately across modern SEO environments. As search ecosystems become increasingly influenced by AI-generated summaries, semantic ranking systems, and conversational search interfaces, organizations require more advanced methods for understanding user intent beyond traditional keyword analysis alone. Hirinfotech helps businesses collect and structure scraped SERP snippets for applications such as: This is particularly valuable for SEO agencies, SaaS companies, ecommerce brands, enterprise marketing teams, and businesses operating across multilingual markets such as the USA, Germany, France, Canada, Australia, and the United Kingdom. Reliable SERP snippet analysis requires scalable scraping infrastructure, localization support, structured data extraction, and ongoing monitoring capabilities to keep pace with rapidly changing search environments in 2026. Best Practices for Using Scraped SERP Snippets Analyze Multiple SERP Features Together Do not rely only on titles. Combine analysis from: This improves classification accuracy. Monitor SERPs Continuously Search intent evolves over time. Regular SERP monitoring helps identify: Use Localization in SERP Analysis Search results differ significantly between countries and languages. Localized scraping improves international SEO decision-making. Combine SERP Data With Content Performance Metrics Businesses should connect SERP intent analysis with: This creates more effective SEO strategies. Frequently Asked Questions What are scraped SERP snippets? Scraped SERP snippets are extracted search result elements such as titles, meta descriptions, featured snippets, FAQs, and related search data collected from search engine results pages. Why is search intent classification important for SEO? Intent classification helps businesses create content that matches what users actually want, improving rankings, engagement, and conversion performance. How do SERP snippets reveal search intent? SERP snippets show how search engines categorize queries based on ranking patterns, content types, metadata, and SERP features. Can SERP scraping improve AI-search optimization? Yes. SERP scraping helps businesses understand semantic search patterns, AI summaries, conversational queries, and answer-engine

Uncategorized

Content Aggregation Data Provider: How Businesses Build Scalable Data Intelligence in 2026

Content Aggregation Data Provider: How Businesses Build Scalable Data Intelligence in 2026 Introduction Businesses increasingly depend on external data to understand markets, monitor competitors, identify opportunities, and improve operational decisions. In 2026, the role of a content aggregation data provider has expanded beyond collecting information from multiple sources. Organizations now expect structured, accurate, continuously updated data that can directly support analytics, automation, and business growth. What Does a Content Aggregation Data Provider Mean for Businesses? A content aggregation data provider collects information from multiple online sources and organizes it into a usable format for business applications. Rather than manually searching through websites, marketplaces, news portals, directories, forums, product pages, or industry platforms, businesses receive centralized and structured datasets designed for specific objectives. Content aggregation may include: The goal is not simply gathering content. The value comes from transforming scattered information into actionable business intelligence. In 2026, companies increasingly need data that can flow directly into CRM systems, analytics platforms, AI models, dashboards, and internal decision workflows. Why Content Aggregation Matters More in 2026 Business environments now move faster than traditional research processes can support. Several developments have increased demand for content aggregation: Growing Data Volumes Public information across websites and digital platforms expands continuously. Manual collection methods struggle to keep pace. AI-Driven Decision Making Organizations increasingly train AI models and business intelligence systems using external datasets. Poor-quality input data often produces unreliable outputs. Real-Time Competitive Monitoring Pricing changes, product launches, regulatory announcements, and market movements can happen within hours rather than weeks. Higher Expectations for Data Accuracy Teams increasingly expect: Raw information alone rarely creates business value. Business Problems Companies Face Without Reliable Content Aggregation Many organizations underestimate the operational impact of fragmented data collection. Common challenges include: Manual Research Consumes Resources Teams often spend large amounts of time gathering information from multiple websites and sources. This creates: Incomplete Market Visibility Businesses using isolated information sources may miss: Inconsistent Data Structures Data gathered from different websites often uses different formats. Examples include: Data teams frequently spend more time cleaning information than analyzing it. Scaling Becomes Difficult Processes that work for small datasets often fail when organizations need: How Web Scraping Supports Content Aggregation Web scraping forms the operational foundation behind many content aggregation systems. Modern web scraping goes beyond extracting text from static web pages. Enterprise-grade implementations often involve: Source Identification Teams determine which platforms provide useful and reliable information. Automated Crawling Systems continuously collect content from selected sources. Data Parsing and Extraction Relevant elements are identified and transformed into structured fields. Examples include: Data Cleaning and Standardization Raw extracted information is processed to remove: Enrichment and Delivery Data may then be enriched with: The result becomes ready for business use. Industry Use Cases for Content Aggregation Data Providers Content aggregation serves multiple industries because nearly every sector depends on external information. E-commerce and Retail Retail businesses use aggregated datasets for: Media and Publishing Media organizations monitor: Real Estate Real estate platforms aggregate: Recruitment and HR Technology Recruitment businesses monitor: Financial Services Financial organizations analyze: Market Research Firms Research teams use aggregated datasets to improve: What Businesses Should Evaluate in a Content Aggregation Partner Choosing a content aggregation provider should involve more than comparing pricing. Decision-makers often evaluate several operational factors. Data Accuracy Processes Questions to consider: Scalability Businesses should understand whether systems support: Source Complexity Handling Modern websites increasingly use: Providers need infrastructure capable of handling these environments. Integration Capabilities Data becomes useful only when it reaches business systems efficiently. Common delivery methods include: Compliance and Responsible Collection Practices Organizations increasingly consider: Compliance considerations have become more important as regulations evolve globally. How Hir Infotech Supports Businesses Using Web Scraping for Content Aggregation Organizations requiring large-scale content aggregation often need more than isolated scraping scripts. They need a managed process that supports long-term data operations. Hir Infotech specializes in web scraping and AI-driven data extraction services designed for businesses that rely on external information as part of strategic decision-making. Its capabilities align closely with content aggregation requirements because aggregation frequently depends on scalable extraction, processing, and delivery pipelines. The company supports businesses through services such as: For organizations in sectors such as e-commerce, market intelligence, media, real estate, and SaaS, content aggregation requirements can quickly become technically complex. Maintaining extraction systems, adapting to source changes, managing quality controls, and supporting ongoing data delivery often require specialized expertise. Rather than treating scraping as a one-time technical task, a structured approach focuses on maintaining data quality, operational reliability, and scalability over time. Businesses operating across India and global markets increasingly look for data partners capable of supporting these ongoing requirements while aligning data collection efforts with practical business outcomes. Best Practices for Implementing Content Aggregation Projects Organizations typically see stronger outcomes when they approach aggregation strategically. Define Business Objectives First Avoid collecting information simply because it is available. Start with questions such as: Prioritize Data Quality Poor-quality information creates expensive downstream problems. Validation and monitoring should be built into workflows. Focus on Integration Data should move directly into operational systems rather than remaining isolated. Plan for Continuous Maintenance Source websites change frequently. Long-term reliability requires: Frequently Asked Questions What does a content aggregation data provider do? A content aggregation data provider collects information from multiple sources, organizes it into structured datasets, and delivers it in formats suitable for business applications such as analytics, market research, and automation. How is content aggregation different from web scraping? Web scraping is the technical process of extracting data from websites. Content aggregation is a broader workflow that includes collection, cleaning, standardization, enrichment, and delivery. Is content aggregation useful for small businesses? Yes. Small businesses can use aggregated data for competitor monitoring, market research, pricing analysis, and identifying growth opportunities without building large internal research teams. What data formats are commonly used in content aggregation projects? Common formats include CSV, JSON, XML, API feeds, cloud storage outputs, and database integrations. How often should aggregated data be updated? The frequency depends on business objectives. Pricing intelligence

Scroll to Top