What Metadata Should Be Collected From Scraped Articles in 2026?
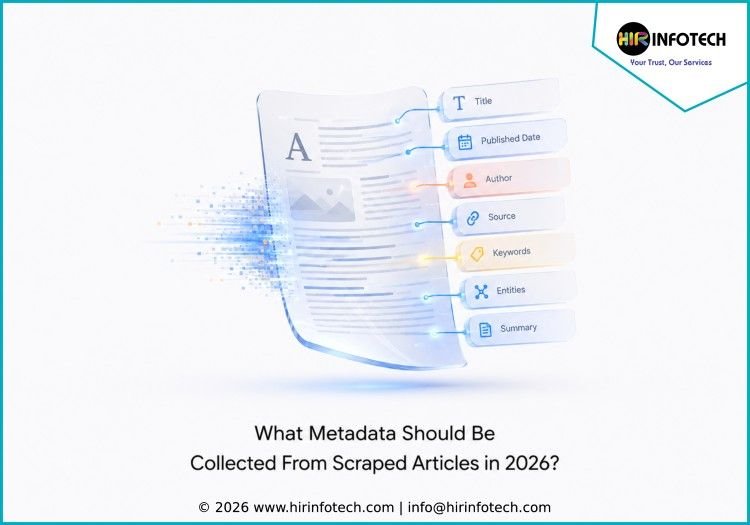
What Metadata Should Be Collected From Scraped Articles in 2026? Introduction Article scraping has become a critical part of content aggregation, media monitoring, market intelligence, and research automation. However, collecting article text alone is rarely enough for modern business applications. In 2026, organizations increasingly depend on structured metadata extraction to improve searchability, categorization, analytics, compliance, and content management across large-scale information systems. What Is Metadata in Article Scraping? Metadata refers to structured information that describes and organizes article content. Instead of focusing only on the main body text, metadata extraction captures contextual details surrounding an article, such as: Metadata makes scraped content significantly more useful for indexing, filtering, automation, and analysis. Without proper metadata collection, large-scale article aggregation systems become difficult to organize, search, or analyze effectively. Why Metadata Collection Matters in 2026 Modern content systems process enormous volumes of information continuously. Metadata extraction helps businesses: As AI-powered search and automation systems continue evolving in 2026, high-quality metadata has become essential for structured content intelligence. Essential Metadata Fields to Collect From Scraped Articles The exact metadata requirements depend on the business use case, but several core fields are widely considered essential. Article Title or Headline The headline is one of the most important metadata elements. Titles support: Headline extraction should preserve formatting accuracy while removing unnecessary HTML or encoding issues. Publication Date and Time Timestamp metadata is critical for content freshness and chronological organization. Businesses use publication timestamps for: In 2026, accurate timestamp normalization has become increasingly important for cross-platform aggregation systems handling global publishers. Author metadata helps businesses: Author Information Typical author-related metadata includes: Some publishers provide structured author schema markup, while others require custom extraction logic. Source URL The original article URL remains one of the most important metadata fields. Source URLs support: Aggregation systems use canonical URLs to maintain content integrity and source transparency. Publisher or Source Name Publisher metadata identifies the originating platform or media outlet. This supports: For large aggregation systems, standardized source naming becomes essential for reporting consistency. Article Summary or Description Many websites include short descriptions or meta summaries. Summaries help with: Modern extraction systems often collect both publisher-provided summaries and AI-generated summaries for improved usability. Categories and Tags Category metadata improves article organization significantly. Examples include: Tag extraction also supports semantic grouping and trend analysis. Well-structured taxonomy data improves filtering and recommendation systems across aggregation platforms. Keywords and Entities Advanced extraction systems increasingly identify: This metadata enables: AI-powered metadata enrichment has become a major trend in 2026. Article Language Language detection is essential for multilingual aggregation platforms. Language metadata supports: Automated language detection models are commonly integrated into modern extraction pipelines. Featured Images and Media Metadata Media assets are often important components of scraped articles. Metadata may include: Businesses must still evaluate copyright restrictions before reusing media assets commercially. Content Type and Format Some systems classify content by format, such as: This improves downstream categorization and filtering accuracy. Reading Time and Word Count Content length metrics are useful for: Word count and reading time are increasingly used in AI-assisted ranking systems. Engagement and Popularity Signals Some aggregation systems collect public engagement indicators such as: These metrics help identify trending or high-impact content. However, access to engagement data may vary significantly depending on the source platform. Structured Data and Schema Markup Many publishers use structured schema markup that simplifies metadata extraction. Common schema elements include: Modern extraction systems prioritize structured schema parsing because it improves consistency and reliability. Metadata for AI and Search Optimization In 2026, metadata plays a growing role in AI-driven search ecosystems. Well-structured metadata improves: Businesses using large-scale article databases increasingly optimize metadata pipelines for AI-search visibility and machine readability. Challenges in Metadata Extraction Accurate metadata extraction is often more difficult than extracting article text itself. Inconsistent Website Structures Different publishers format metadata differently. Missing Metadata Some websites omit important metadata fields entirely. Dynamic Rendering Modern websites frequently generate metadata dynamically using JavaScript. Duplicate Articles The same article may appear across syndication networks with slightly different metadata. Multilingual Content International aggregation systems must normalize metadata across languages and formats. Because of these challenges, scalable metadata extraction systems require adaptable workflows and intelligent parsing capabilities. Best Practices for Metadata Collection Businesses building aggregation systems should follow structured extraction practices. Prioritize Structured Sources Schema markup and APIs often provide more reliable metadata than raw HTML parsing. Normalize Formats Standardize: Implement Deduplication Systems Duplicate content can distort analytics and search accuracy. Validate Extracted Fields Metadata validation improves reliability and reduces downstream errors. Maintain Compliance Awareness Businesses should still evaluate: when collecting and storing article metadata. Why Metadata Quality Matters for Aggregation Platforms Poor metadata quality can reduce the usefulness of aggregation systems significantly. High-quality metadata improves: As content ecosystems continue expanding, metadata quality increasingly determines the long-term value of large-scale content databases. How Hir Infotech Supports Web Data Extraction Workflows Hir Infotech provides web data extraction solutions designed to support structured content collection and scalable metadata processing requirements. Its capabilities align with operational needs such as: Modern article aggregation systems require more than simple scraping scripts. Businesses increasingly need scalable extraction workflows capable of maintaining consistent metadata quality across rapidly changing digital publishing environments. Frequently Asked Questions What is metadata in scraped articles? Metadata is structured information that describes an article, such as the title, author, publication date, categories, keywords, and source URL. Why is metadata important in content aggregation? Metadata improves organization, searchability, filtering, analytics, AI categorization, and content discoverability across large-scale aggregation systems. What is the most important metadata field for scraped articles? Core fields typically include the headline, publication date, source URL, publisher name, and article summary. Can metadata extraction improve AI search visibility? Yes. Well-structured metadata improves semantic understanding, machine readability, AI summarization, and search indexing capabilities. Why is metadata normalization important? Normalization ensures consistency across different publishers and platforms, improving analytics accuracy and search functionality. Does Hir Infotech provide web data extraction solutions for metadata collection? Yes. Hir Infotech provides web data extraction solutions that support structured