A BLACK FRIDAY BONUS FOR YOUR BUSINESS

15% OFF

Web Scraping

A Responsible Web Data Collection Checklist for AI and Analytics Teams
Web Scraping

A Responsible Web Data Collection Checklist for AI and Analytics Teams

A Responsible Web Data Collection Checklist for AI and Analytics Teams Web data can support market analysis, product research, forecasting, and AI development. But a collection project is not ready simply because a website can be accessed or a crawler can extract the fields. Teams also need to decide what they are collecting, why they need it, whether the source and access method are appropriate, how the data will be used downstream, and when it should be deleted. This checklist is for data leaders, AI product teams, privacy and legal teams, and procurement managers assessing web-data projects in the European Union or United Kingdom. It is an operational decision guide, not legal advice. The outcome depends on the data, source, access method, purpose, jurisdiction, and downstream processing. Start with the project, not the crawler Before engineering begins, write a short project description that answers these questions: “Collect data for AI” is too broad to guide a responsible project. Define the intended use clearly enough that reviewers can assess necessity, access, retention, and likely impact. 1. Identify personal and sensitive data Review the pages and fields the proposed collection could reach. A dataset may contain personal data even when the project is aimed at companies, products, or market trends. Names, work details, user-generated posts, profile information, and identifiers can relate to identifiable people. Data can also become personal when combined with other information or used to infer something about an individual. Decide whether special-category personal data could be collected, even incidentally. Under the GDPR, processing such data is restricted and requires specific analysis. Do not assume that a project avoids this question because the source page is public or the team does not intend to collect sensitive information. Checklist: 2. Test the purpose and legal basis For projects involving personal data, document the purpose and the analysis supporting the proposed processing before collection begins. The EU GDPR sets requirements for personal-data processing, including purpose limitation, data minimization, accuracy, and storage limitation. Public availability by itself does not answer whether a specific collection and use are appropriate. For web-scraped personal data used to train generative-AI models, the UK ICO’s published position says that legitimate interests may be available under current practices only where the organisation can meet the three-part test, including necessity. The ICO also expects developers to explain why other available collection methods are unsuitable. That position is specific to generative-AI training; do not apply it automatically to every AI or analytics use case. For EU projects, the EDPB’s Guidelines 03/2026 address scraping in the context of generative AI. At the time of writing, the guidelines are open for consultation and are not final. Review their status again before relying on them. Checklist: 3. Review each source and access method Evaluate sources individually. A public webpage, a licensed dataset, an official API, and a login-protected service may come with different conditions and risks. Review applicable terms, licenses, technical restrictions, and source-specific rules before selecting a collection method. If access depends on an account, paywall, CAPTCHA, or another access control, do not attempt to bypass it. Pause and obtain authorization or use an approved access method. Where an official API or licensed feed is available, assess whether it meets the project’s requirements. Keep source review separate from privacy review. Permission or technical access to a source does not by itself establish a lawful basis for processing personal data or permission for every downstream use. Checklist: 4. Collect only what the project needs Translate the project purpose into a field list before collection. For each field, explain why it is needed and how it will be used. Avoid gathering broad page content or unrelated identifiers merely because they are easy to extract. Build minimization into the collection and processing plan. Depending on the use case, this might mean excluding unnecessary fields, filtering out certain page types, limiting access, or transforming data before wider use. Safeguards should be designed for the actual dataset and workflow rather than copied from a generic checklist. 5. Maintain a source and data-quality record Data quality affects whether an analysis can be trusted. Preserve enough information to understand what was collected, from where, and when. The EDPB’s 2026 draft guidance recommends reliable sources, recording timestamps, and validating data before using it in AI training. Treat that as draft guidance in its stated generative-AI context and confirm its status before publication or operational reliance. Record Why it helps Source reference Lets reviewers trace a record back to its origin. Collection date or timestamp Shows when the information was observed. Fields collected Allows teams to compare the collection with the approved scope. Validation checks and exceptions Documents known gaps, conflicting values, or records needing review. Downstream destination Shows which systems, teams, or model workflows received the data. Do not describe data as “verified” without saying what was checked and when. A quality label should reflect an actual validation method, not just a successful extraction. 6. Decide retention and downstream use before collection Set a retention rule tied to the stated purpose. Identify who owns deletion or review, how backups and working copies are handled, and what happens when data is no longer needed. Avoid leaving retention decisions until after data has spread across analysis environments, model pipelines, and vendor systems. Map the full data path: collection, storage, cleaning, analysis, model development, evaluation, deployment, and sharing. A dataset collected for one purpose should not silently move into a different purpose. Review whether teams or providers have the roles, agreements, access controls, and documentation required for their part of the workflow. For AI projects, consider whether personal information could be memorized, inferred, or reproduced in outputs. Assess the model and use case, and document safeguards and response procedures for the risks identified. 7. Use a go, revise, or stop decision Before collection begins, record an outcome that the project team and reviewers can understand: A “proceed” decision is not a permanent approval. Reassess when the source changes, the collection expands, a new
How to Audit B2B Contact Data Before a Sales Campaign
Web Scraping

How to Audit B2B Contact Data Before a Sales Campaign

How to Audit B2B Contact Data Before a Sales Campaign A sales campaign can have a clear audience, a thoughtful message, and a well-planned schedule—and still start with the wrong contact data. Records may be incomplete, duplicated, outdated, or unrelated to the campaign. A contact may have changed roles, a company may no longer fit the target market, or an address may have no clear source or verification date. A B2B contact data audit helps sales operations, RevOps, demand generation, and CRM teams check those records before they are used. The goal is not to make every record look complete. It is to decide which records are sufficiently supported for the intended use, which need more research, and which should be suppressed or removed. What should a B2B contact data audit check? Start by reviewing each record against the campaign’s actual requirements. A useful audit looks at several separate dimensions: Keep data quality and permission to contact as separate decisions. A record can be accurate and still be unsuitable for a particular campaign. 1. Define the campaign’s acceptance criteria Before opening a spreadsheet or running a CRM report, write down what qualifies a record for this campaign. Include the target market, relevant industries, company characteristics, roles, required fields, and any exclusions. If different teams use different definitions of a qualified account or contact, resolve those differences before auditing. Also identify the fields that are essential versus helpful. For example, a campaign may require a company name, country, role, and a documented source. A direct phone number might be helpful but not required. Clear criteria prevent teams from treating every missing field as equally important. 2. Check completeness and consistency Review the fields your campaign depends on. Look for blank values, inconsistent country or industry labels, outdated job titles, and company names recorded in multiple ways. Check whether the contact is associated with the right account and whether the CRM has a defined way to flag former employees, role changes, or uncertain matches. Standardize values before comparing records. For example, inconsistent country names or variations in company naming can hide duplicates and make segmentation unreliable. Preserve the original values or an audit trail when your process requires it. 3. Review sources and verification dates A record should have enough provenance for a reviewer to understand where its key details came from and when they were checked. Depending on the field and your approved process, sources might include a company’s public website, a business directory, an enrichment provider, or an internal CRM update. Do not treat a source label such as “web” or “database” as a complete audit trail if it does not let your team assess the source. Record a source reference and verification date where appropriate. If a field cannot be supported, mark it for review rather than presenting it as confirmed. 4. Deduplicate people and accounts Duplicate records can cause multiple representatives to contact the same person, distort campaign reporting, and make account histories harder to follow. Compare records using the identifiers your organization is allowed to use, such as a normalized business email, contact name and company, or an existing CRM identifier. Do not merge records automatically when the match is uncertain. Similar names, shared inboxes, subsidiaries, and company rebrands can create false matches. Route ambiguous cases to a reviewer and retain the relevant history when consolidating records. 5. Assess role and company relevance A contact can be real and current but still be a poor fit for the campaign. Check whether the person’s responsibilities connect to the offer and whether the company meets the campaign criteria. A senior title alone does not prove decision-making authority or interest. Use evidence-based labels such as “matches target role,” “role unclear,” or “outside target.” These labels help sales teams distinguish a confirmed fit from an assumption based on a title or company name. 6. Separate contact-data checks from outreach eligibility Valid-looking contact details do not establish that a campaign is appropriate or permitted. Before releasing an audited list, check applicable privacy and electronic-marketing rules, the organization’s internal policies, source restrictions, and suppression records. Keep opt-outs and other suppression instructions available to the people and systems preparing the campaign. Rules differ by market and recipient type. For example, the UK ICO explains that electronic marketing rules can differ for corporate and individual subscribers, while personal data about a business contact may still be subject to UK GDPR requirements. Canada’s business-to-business exemption has conditions, and US commercial email is covered by CAN-SPAM requirements. Get jurisdiction-specific advice when the campaign or data source raises uncertainty. 7. Give every record a clear outcome Use a small set of audit outcomes that sales and operations teams understand. For example: Outcome Meaning Next step Ready for review Required fields and supporting checks are present. Confirm campaign eligibility and apply normal approval steps. Research needed A required detail is missing, stale, or uncertain. Assign a reviewer or approved research workflow. Suppress or remove The record is excluded, duplicated, unsupported, or otherwise unsuitable. Apply the relevant suppression or data-management process. These outcomes are workflow labels, not a legal determination. A “ready for review” record still needs the campaign’s normal eligibility checks. Use a sample audit before processing the full list If a list is large or comes from multiple sources, review a representative sample first. Check whether your criteria are clear, whether reviewers reach consistent decisions, and whether the source and date fields provide enough context. Adjust the audit instructions before applying them at scale. After the audit, keep a record of the criteria, fields checked, review date, and unresolved issues. This gives sales operations and RevOps a repeatable way to refresh data and investigate questions later. Make data quality part of campaign readiness A B2B contact data audit is most useful when it is tied to a specific campaign and a documented decision process. Check fit, completeness, freshness, provenance, duplicates, and use eligibility separately. Then route records for review, further research, or suppression based on evidence. For

How to Match Competitor Products Before Comparing Ecommerce Prices
Web Scraping

How to Match Competitor Products Before Comparing Ecommerce Prices

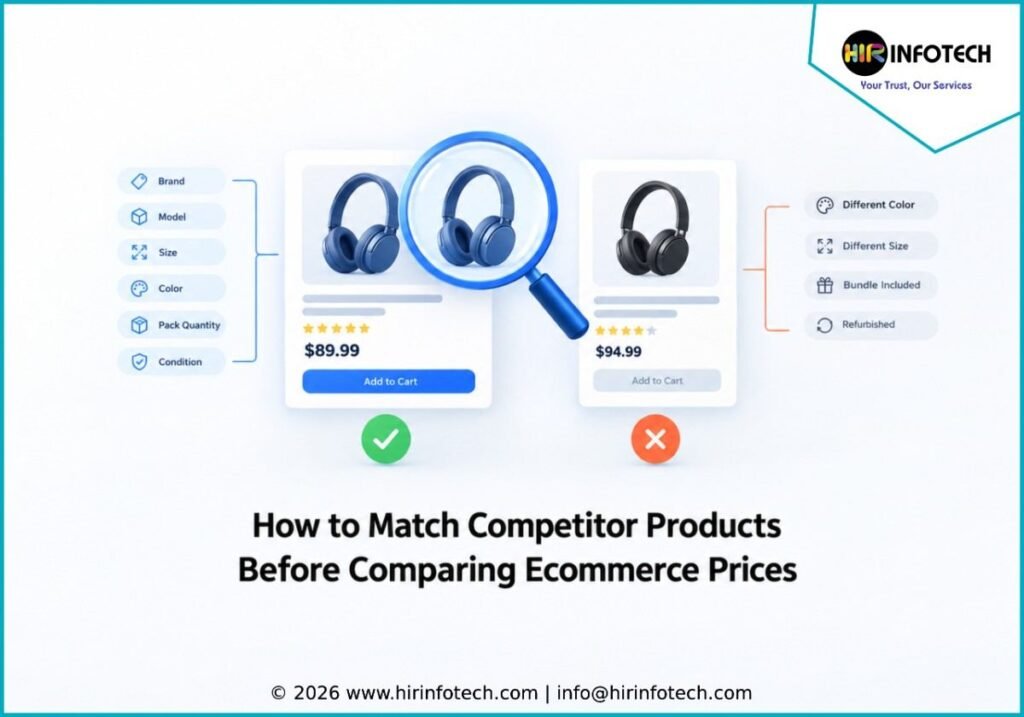
How to Match Competitor Products Before Comparing Ecommerce Prices A competitor’s listing may look like the same product as yours and still be a poor price comparison. It might have a different size, model, color, bundle, condition, seller, or delivery location. If those differences go unnoticed, a price report can compare offers that customers would not consider equivalent. Product matching is the process of deciding whether two listings represent the same item or a sufficiently similar alternative for a specific analysis. The goal is not to match as many listings as possible. It is to make comparisons that are useful for the decision being made—and to leave uncertain matches visible for review. Start by defining what “comparable” means Before matching listings, decide what the pricing team needs to compare. An exact match may require the same manufacturer product, variant, size, and pack quantity. A category analysis may allow a broader comparison between similar products, but it should label those results as substitutes rather than identical items. That distinction matters. A 1.5-litre appliance and a 1.7-litre appliance may be alternatives in a category review, but they are not the same item. Their prices should not be combined under an “exact competitor price” label. Use identifiers as strong evidence, not as the whole decision When available, compare standardized identifiers such as a GTIN, UPC, EAN, or manufacturer part number (MPN), along with the brand. GS1 describes a GTIN as an identifier for trade items. Google Merchant Center also advises merchants to provide correct product identifiers and warns against guessing or using identifiers from similar products. (GS1 on GTINs; Google Merchant Center on product identifiers) Identifiers are valuable when they are correct and refer to the same product level. A product can have separate identifiers for different sizes or colors. A multipack or bundle can also represent a different trade item from a single unit. Confirm the identifier’s meaning before treating two listings as identical. A seller’s internal SKU can help identify a listing in that seller’s catalog, but it should not automatically be treated as a manufacturer-wide identifier. If identifiers are absent or inconsistent, compare additional attributes and lower the match confidence when evidence is weak. Compare the attributes that can change the offer Titles are useful for finding candidate listings, but they are not sufficient proof of a match. Product titles may omit important details, use abbreviations, or place the same attributes in a different order. Compare attributes that matter to the product category, such as: Not every attribute carries equal weight. A color difference may be minor for one category and commercially important for another. A model-number mismatch may be a decisive reason to reject a match even if the titles are nearly identical. Separate product identity from the seller’s offer Once the product itself is identified, compare the offer attached to it. The same item can be sold by different sellers with different prices, shipping costs, promotions, stock status, or delivery conditions. Before comparing prices, define whether the analysis includes shipping, taxes, coupons, membership-only discounts, or other charges. Keep the country, currency, and delivery location attached to each observation. A displayed price is a dated observation of an offer; it does not necessarily represent the final amount every customer will pay. Record the observation time and the listing source. This helps teams distinguish a genuine price change from a change in location, promotion, or stock status. Use a match decision table The following examples are illustrative. They show how a team might classify listings before using them in a price comparison. Listings being compared Suggested decision Reason Same brand, model, size, and valid product identifier Potential exact match; verify the offer details Strong identity evidence, subject to checking condition, pack, and seller offer. Same appliance model, but different capacity Do not label as an exact match Capacity is a meaningful product difference; it may be a substitute for a separate category analysis. Single camera body compared with a camera-and-lens bundle Do not compare as the same offer The bundle includes additional items that change the offer and price. Same product model, but one listing is refurbished Separate by condition Condition affects the offer and buyer expectation. Similar titles but no reliable identifier or matching specifications Manual review or no match Title similarity alone does not establish product equivalence. Give every match a confidence status A useful system should not force every candidate into a yes-or-no result. It can label records as exact match, probable match, review required, or no match. The labels should have written rules so that pricing analysts know how each group may be used. For example, a confirmed exact match might feed a direct price comparison. A probable match could appear in a separate review queue. A no-match record should not silently enter an exact-match report. Review a sample of accepted and rejected matches. Track false matches—different products treated as the same—and missed matches—equivalent products treated as different. This helps teams refine their rules without claiming that any automated method is perfectly accurate. Keep the matching logic auditable For each decision, retain the source listing, observed product attributes, identifiers found, match status, and any reviewer decision. If a match is changed later, keep enough history to understand why. This record is especially useful when listings change. A seller may update a title, replace an image, add a bundle, or change the product variant. The team can then reassess the match using the evidence rather than relying only on an earlier decision. Short product-matching checklist Hir Infotech describes product matching and competitor price monitoring as part of its Price Intelligence services. Confirm any specific claims about matching methods, marketplace coverage, data frequency, or accuracy with the team before including them in promotional copy. (Hir Infotech Price Intelligence) Price comparisons are only as useful as the product and offer comparisons behind them. Establish what counts as an equivalent item, preserve the evidence for each match, and keep uncertain listings separate until they have been reviewed.

How to Detect Stale or Broken Data in a Web Scraping Pipeline
Web Scraping

How to Detect Stale or Broken Data in a Web Scraping Pipeline

How to Detect Stale or Broken Data in a Web Scraping Pipeline A web data pipeline can keep running while its output quietly becomes less useful. A source page changes, an extracted field goes blank, a transformation misreads a value, or a delivery step fails. If the only health check is “the job completed,” these problems may reach a dashboard, database, or business team before anyone notices. Reliable monitoring checks each stage of the pipeline: whether the source was accessible through the intended method, whether the expected data was extracted, whether the records passed validation, and whether the output reached its destination. This makes it easier to identify where a failure started and what should happen next. First, distinguish stale data from broken data Stale data may have been collected successfully, but it is older than the use case allows. For example, a scheduled feed may still contain yesterday’s values when a team needs a more recent observation. Broken data is incomplete, malformed, incorrectly transformed, or not delivered as expected. A job can report success and still produce broken data if a required field disappears or changes format. These problems need different checks. A timestamp helps assess freshness, but it does not prove that the values are correct. A schema check can confirm that a field exists, but it cannot confirm that the field contains the intended meaning. Check four stages of the pipeline 1. Source access Record whether the expected source was reached and whether the response was consistent with the access method you are authorized to use. Track meaningful changes in response status, page structure, or source availability. A blocked or restricted response is not a signal to bypass access controls. Pause and review the source’s terms, access requirements, and approved collection method before proceeding. 2. Extraction Check whether required fields were captured and whether their values look plausible. A source change may leave a field empty, shift content into a different location, or return a label where the pipeline expected a value. Track field-level completeness, unexpected nulls, and changes in data type. A successful page load is not enough if the records no longer contain the information the downstream task depends on. 3. Transformation and validation Compare the raw extracted values with the transformed output. Parsing, normalization, deduplication, and field mapping can introduce errors even when extraction worked as intended. Validation rules should reflect the use case. They might check required fields, date formats, value ranges, duplicate identifiers, relationships between fields, or whether the current schema matches the expected one. Great Expectations describes schema drift, missing values, and duplicate data as possible ingestion issues; it also recommends validating data before problems propagate downstream. (Great Expectations on ingestion checks) 4. Delivery Confirm that the validated output reached its intended destination and that the destination accepted it. A good extraction can still fail at the final step because of a format mismatch, permissions issue, or downstream load error. Keep the collection run, validation result, and delivery status connected through an identifier or log entry. That record helps teams determine whether a problem began at the source or later in the pipeline. Build checks around the data’s expected behavior Before monitoring a pipeline, define what “normal” means for the use case. Consider how often the source should be checked, which fields are essential, what volume variation is expected, and which changes require a review. For example, a listing directory may change slowly, while product availability can change more frequently. A single freshness interval or record-count threshold may not fit both. Set checks according to the business need and the behavior of each source. AWS Glue Data Quality documents checks for freshness and completeness. These are useful examples of measurable data-quality dimensions; teams should choose checks that fit their own platforms, data, and operating requirements. (AWS Glue Data Quality; completeness checks; file freshness checks) Illustrative validation table The checks below are examples, not a Hir Infotech project or a universal set of thresholds. Define acceptable limits for the particular source and use case. Pipeline stage Example check What a failure might indicate Practical response Source access Did the source respond as expected through the approved access method? Source outage, changed access requirements, or a permissions issue Pause and investigate source access and terms; do not bypass restrictions. Freshness Is the collection timestamp within the interval required for this use case? Missed run, delayed source update, or stale output Check the last successful collection and delivery times. Extraction Are essential fields present at the expected rate? Page layout change, missing source values, or extraction mapping issue Compare raw source content with the extracted record. Transformation Do formats, types, ranges, and relationships match the rules? Parsing, normalization, or mapping error Compare raw and transformed values; correct the rule if needed. Volume and duplicates Is the record count within the source’s normal range, and are identifiers duplicated unexpectedly? Partial capture, duplicate processing, or a genuine source change Compare with historical runs and review a sample before delivery. Delivery Did the destination accept the expected output? Format, permission, connection, or downstream processing issue Check delivery logs separately from extraction results. Use a triage sequence when a check fails Common monitoring mistakes Make pipeline health visible A useful monitoring view connects each run to its source, collection time, validation results, and delivery outcome. It should make it possible to answer four questions: Was the source reached? Did extraction return the expected fields? Did the records pass the relevant checks? Did the output reach its destination? Hir Infotech describes web data collection, validation, and structured delivery on its Data Collection Services page. Confirm any specific claims about monitoring, alerting, refresh frequency, or error handling with the team before including them in promotional copy. Pipeline reliability comes from checking the data at each stage and responding to failures with evidence. A job status is one signal; field quality, freshness, transformation results, and delivery confirmation complete the picture.

What Makes External Web Data Ready for AI Agents_ A Practical Quality Checklist
Web Scraping

What Makes External Web Data Ready for AI Agents? A Practical Quality Checklist

What Makes External Web Data Ready for AI Agents? A Practical Quality Checklist AI agents can retrieve information, compare records, and take actions across business workflows. But their usefulness depends in part on whether the data they access is current, understandable, and trustworthy. In an ongoing survey with more than 540 responses, The Modern Data Company reported that 57.3% of respondents were piloting or running AI agents, while 8.4% said the data feeding their AI systems was trustworthy enough for production. These findings are an early industry signal, not a universal measure of AI readiness. They point to a practical question for data teams: can an AI system interpret the data it receives and trace it back to a source? (The Modern Data Company survey findings) External web data can support tasks such as market monitoring, product comparison, and business research. Before feeding it into an AI or analytics workflow, teams should assess more than whether the data has been collected. They should check its structure, freshness, source history, meaning, permitted use, and what happens when something changes. AI-ready data needs structure and context A dataset is not ready for AI just because it is machine-readable. A spreadsheet may have consistent columns and still contain stale prices, duplicate companies, ambiguous product names, or values with no record of where they came from. McKinsey’s guidance on AI data readiness highlights the need for data with clear structure, versioning, and context. It also notes that quality controls need to extend through transformations and retrieval, since incomplete or outdated information can affect what an AI system uses. (McKinsey’s AI data-readiness guidance) For external web data, that means evaluating the path from source to use. The checklist below can help teams identify gaps before connecting a dataset to an AI agent, retrieval system, dashboard, or other workflow. A practical checklist for external web data 1. Define the use case Start with the task. Is the system summarizing product changes, comparing market offerings, identifying business accounts, or answering questions from public sources? The use case determines which fields matter, how fresh the data needs to be, and what errors could affect a decision. A daily update may be suitable for some market research. A rapidly changing availability feed may require a more frequent schedule. Set freshness requirements based on the use case rather than relying on a generic “real-time” claim. 2. Record where each value came from Keep source information alongside the extracted data. Depending on the use case, that might include the source name, URL, collection timestamp, date shown on the source, and the method used to obtain the value. Provenance helps teams investigate differences between sources, distinguish observed facts from inferred values, and review whether a record is still useful. If a value cannot be traced to a source or collection event, users may not know whether to trust it. 3. Check completeness and field quality Review whether required fields are present and usable. A product record with no model identifier may be difficult to match accurately. A business record without a location or source date may not be suitable for regional analysis. Use checks that fit the data: required-field checks, valid date formats, duplicate detection, range checks, and comparisons between related fields. Mark missing data as missing instead of filling it with assumptions. 4. Normalize formats and preserve the original values External sources often represent the same information differently. Dates, currencies, product sizes, company names, and locations may use different formats. Normalization makes records easier to compare, but teams should preserve the raw value alongside the cleaned value. Keeping both forms lets reviewers see what changed during processing. It also reduces the chance that a transformation removes a distinction that matters to the use case. 5. Resolve entities carefully AI workflows often need to recognize when two records refer to the same company, product, or location. Similar names alone may not establish a match. Teams may need reliable identifiers or a combination of attributes. Uncertain matches should be flagged for review rather than treated as confirmed. For example, two listings with similar product titles might differ by pack size, model year, seller, or included accessories. Merging them without checking those details can produce misleading comparisons. 6. Add business meaning A field needs a clear definition. “Price” could mean list price, sale price, a price before tax, or a price shown to users in a specific location. “Availability” could mean in-stock status, estimated delivery, or whether a listing is visible. Document definitions, units, relationships, and limitations so people and AI systems interpret values consistently. McKinsey also recommends maintaining context and quality across data transformations and retrieval, not only at collection. (McKinsey on data quality in AI workflows) 7. Review source permissions and intended use Before collecting or reusing data, review the source, access method, applicable terms, data type, jurisdiction, and intended downstream use. If personal data is involved, the relevant legal requirements can depend on those details. Do not assume that information being publicly visible means every collection method or use is permitted. Where obligations are unclear, involve qualified legal or privacy reviewers. This checklist is operational guidance, not legal advice. 8. Monitor the data after delivery A one-time quality review cannot catch every change in a source or pipeline. Monitor for missing fields, unexpected value shifts, duplicate spikes, stale timestamps, and changes in incoming record structure. Set review thresholds that reflect the business risk. McKinsey notes that AI data observability may need to include whether retrieved content is complete and current, and whether outputs remain aligned with source material as it changes. (McKinsey on observability and freshness) Example data-quality review The table below is illustrative. It shows questions a team might ask before using an external dataset; it does not describe a specific Hir Infotech project or customer workflow. Check Example question Possible action Freshness When was this value collected, and how often does the use case require an update? Store collection and source dates; define a review interval. Completeness Are

Web Scraping

When Should You Use Web Scraping for Data Migration in 2026?

When Should You Use Web Scraping for Data Migration in 2026? Data migration projects are often more complex than simply moving records from one database to another. Many organizations still rely on legacy portals, supplier websites, online directories, customer-facing platforms, and systems that lack export functionality or API access. In these situations, web scraping can become a practical and efficient solution for collecting and migrating critical business data. Understanding when to use web scraping for data migration helps organizations reduce manual effort, improve data accuracy, and accelerate modernization initiatives. Understanding the Role of Web Scraping in Data Migration Web scraping is the process of automatically extracting structured information from websites, web applications, online portals, and other web-accessible systems. In the context of data migration, web scraping enables businesses to collect information from sources where direct database access, export tools, or APIs are unavailable. Traditional migration projects typically rely on database exports, ETL pipelines, APIs, or flat-file transfers. However, these methods are not always possible when data resides in outdated systems or third-party platforms. Web scraping becomes valuable when organizations need to: As businesses continue digital transformation efforts in 2026, web scraping has become an increasingly important part of migration strategies, particularly when conventional extraction methods are unavailable. When Web Scraping Is the Right Choice for Data Migration Not every migration project requires web scraping. However, there are several situations where it becomes the most practical and cost-effective approach. Legacy Systems Without Export Capabilities Many older platforms were never designed with modern migration requirements in mind. Some systems lack CSV exports, database backups, or API integrations altogether. When critical business data is accessible only through a user interface, web scraping can systematically extract records while preserving important information required for migration. Website-to-Database Migration Projects Organizations often need to move content from websites into centralized databases, CRM platforms, data warehouses, or content management systems. Examples include: Rather than manually copying thousands of records, web scraping can automate collection and preparation for migration. Third-Party Platform Data Extraction Businesses frequently store operational information on external platforms that do not provide adequate export functionality. Examples include: When organizations need to consolidate this information into internal systems, web scraping may provide the only practical extraction method. Multi-Source Data Consolidation Many migration projects involve combining data from multiple websites and online platforms into a unified database. Web scraping can automate collection from numerous sources while applying standardization and validation rules before loading data into the destination environment. Key Benefits of Using Web Scraping for Data Migration When implemented correctly, web scraping provides several advantages that can significantly improve migration outcomes. Reduced Manual Work Manual data collection is time-consuming, expensive, and prone to human error. Automated scraping dramatically reduces the labor required to gather large datasets. Faster Migration Timelines Large-scale migration projects can take months when data extraction relies on manual processes. Automated scraping accelerates collection, transformation, and preparation activities. Access to Otherwise Inaccessible Data One of the most significant benefits of web scraping is the ability to extract information from systems that do not provide APIs or export tools. This capability allows businesses to migrate data that would otherwise remain locked within outdated platforms. Improved Data Consistency Modern scraping workflows can include validation, normalization, duplicate detection, and formatting checks before migration begins. This helps organizations improve data quality before records reach the target database. Scalability Whether migrating hundreds of records or millions of data points, web scraping solutions can be designed to handle large-scale extraction efficiently. Scalable automation is particularly valuable for enterprise migration projects involving complex datasets. Important Considerations Before Using Web Scraping for Migration While web scraping offers substantial benefits, organizations should carefully evaluate several factors before making it part of a migration strategy. Data Quality Assessment Extracted data should undergo thorough validation before migration. Missing fields, inconsistent formatting, duplicate records, and outdated information can negatively affect the destination system. Data cleansing and transformation processes should be included in every migration workflow. Website Structure Stability Scraping depends on the structure of web pages and applications. Significant interface changes can affect extraction processes. Organizations should ensure that scraping solutions are designed to handle structural updates and ongoing maintenance requirements. Compliance and Data Governance Businesses must evaluate applicable regulations, contractual obligations, and data governance requirements before extracting information from any platform. Responsible data collection practices should always align with relevant laws, terms of service, privacy requirements, and organizational policies. Transformation Requirements Data migration rarely involves direct transfer from source to destination. Most projects require: These processes should be integrated into the migration workflow to ensure successful implementation. Long-Term Data Maintenance Organizations should determine whether scraping is required as a one-time migration activity or as part of an ongoing synchronization process. This decision influences architecture, monitoring requirements, and automation strategy. How Hirinfotech Supports Web Scraping for Data Migration Projects For organizations facing migration challenges involving inaccessible websites, legacy portals, supplier systems, or platforms without export functionality, Hirinfotech provides specialized web scraping solutions designed to support reliable data migration initiatives. Its capabilities focus on extracting structured information from complex web environments and preparing that data for migration into modern databases, CRM platforms, ERP systems, analytics environments, and cloud-based applications. Rather than treating data extraction as an isolated task, effective migration projects require a broader workflow that includes data collection, validation, cleansing, transformation, deduplication, and schema mapping. Hirinfotech supports these requirements through customized scraping workflows aligned with business objectives and destination system requirements. Organizations often encounter migration challenges involving large product catalogs, customer directories, supplier information, marketplace data, business listings, or records trapped inside outdated web interfaces. By automating extraction and preparation processes, web scraping can significantly reduce manual workload while improving migration efficiency. As businesses continue modernizing technology infrastructure in 2026, specialized web scraping services can help overcome common migration barriers and enable smoother transitions to new platforms, databases, and digital ecosystems. Frequently Asked Questions Can web scraping replace traditional data migration methods? No. Traditional methods such as APIs, database exports, and ETL pipelines remain preferred when available.

Scroll to Top